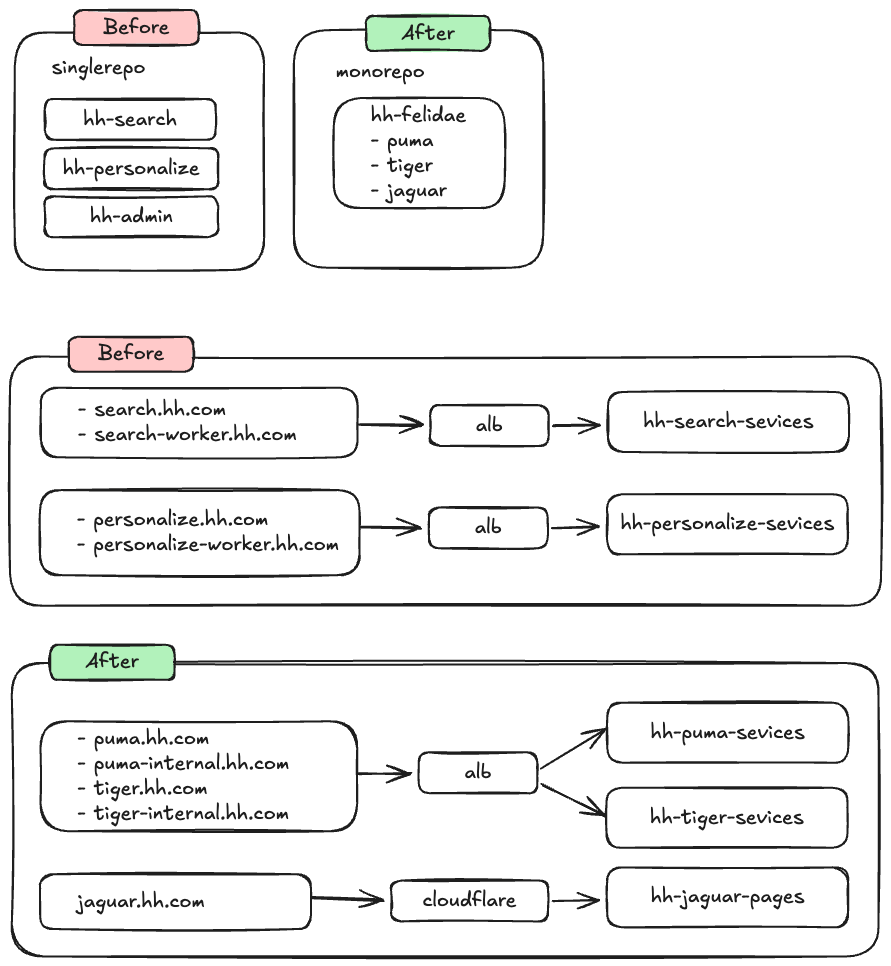


- Microservices Architecture: Separated concerns with Jaguar (frontend), Tiger (core backend), and Puma (search service)
- Event-Driven: Kafka-based event streaming for asynchronous data processing
- Multi-Database: Separate databases for different concerns (legacy, warehouse, application)
- GraphQL First: All client-server communication through GraphQL APIs
- Background Processing: BullMQ for async job processing and data pipelines
- ML Integration: AWS Personalize for recommendation engine
- Search Optimization: OpenSearch with Metarank for intelligent search and ranking
- Monorepo Structure: Turborepo for efficient build and development workflow
- Type Safety: End-to-end TypeScript with generated GraphQL types
- Observability: Rollbar for errors, Elastic APM for performance monitoring
- Admin UI for content management
- Banner and section management
- Restaurant tag management
- User and analytics dashboards
- File upload management
- User authentication and authorization
- CMS content management
- Restaurant data processing
- ML training data preparation
- AWS Personalize integration
- Multi-database orchestration
- Background job coordination
- Restaurant search functionality
- OpenSearch index management
- Search result ranking (Metarank)
- Search suggestions and autocomplete
- Restaurant discovery and filtering
- Feature flag management
- A/B testing experiments
- Progressive rollouts
- Learning-to-rank engine
- Personalization signals
- Ranking model training
- Event streaming platform
- Data pipeline coordination
- Change data capture (CDC)
- S3 data archival
- Full-text search engine
- Restaurant indexing
- Faceted search
- Geospatial queries